
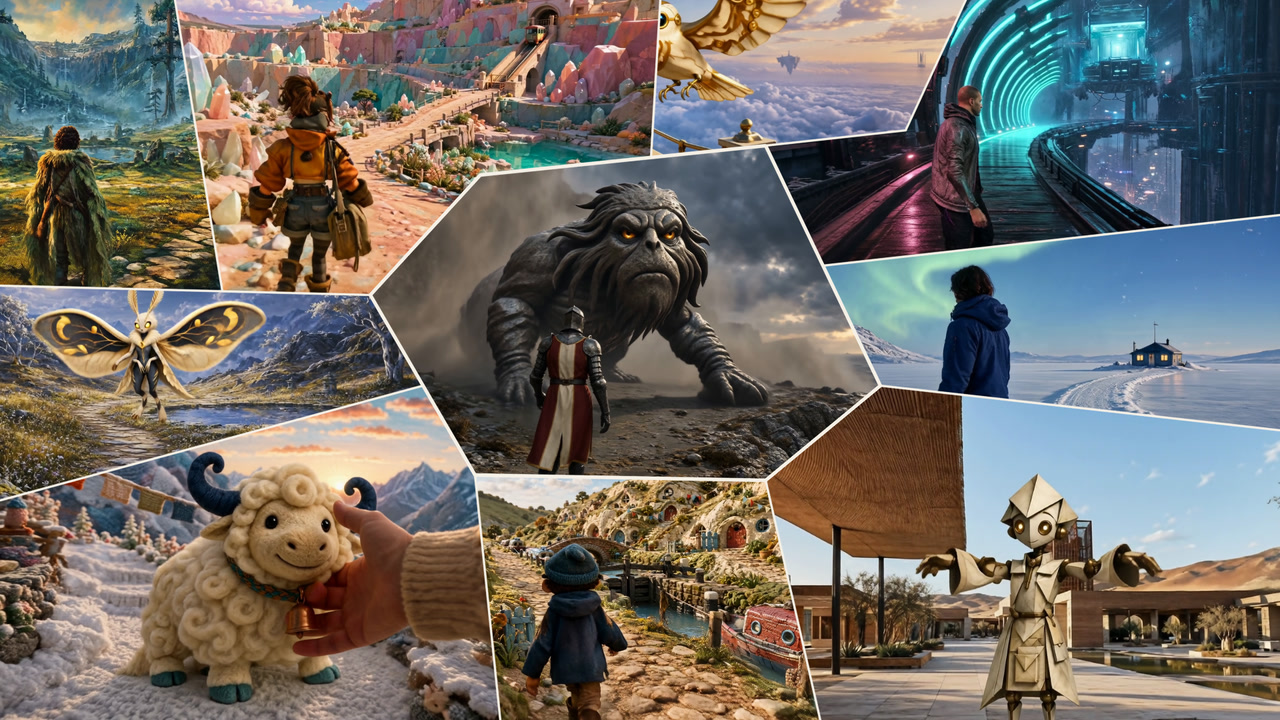
CAMERA × LANGUAGE × VISUAL REFERENCE
01 / THE FILM
See ENUMA in motion.
Full research demo · 1:46 · Silent
02 / INTERACTIVE WORLDS
Choose the next move.
Your move changes what happens next.
03 / REF2VID
Build a world from references.
Character + scene → controllable video.
LONG ROLLOUTS30 SECONDS / 08 CASES
MORE WORLDS8 SECONDS / 08 CASES
04 / TEXT EVENT
Say what happens.
Language changes the world in motion.
LONG ROLLOUTS30 SECONDS / 08 CASES
MORE EVENTS8 SECONDS / 08 CASES
05 / REF EVENT
Show what enters the scene.
Starting frame + event reference → video.
06 / INTERACTION
Act on the world.
Objects, tools, and physical actions.
07 / EMBODIED
Worlds for agents.
Robot actions and navigable spaces.
Pre-recorded model outputs · Select a video to watch the full clip.
One model.
Many forms of control.
Camera. Language. Visual reference.
ENUMA / TECHNICAL REPORT
Unifying Camera, Language, and Visual Controls for Interactive World Modeling
Read abstract
ENUMA is a unified interactive world model supporting camera trajectories, language events, and visual references. Reference Forcing adapts a bidirectional video generator to chunk-wise causal generation, then distills it for efficient rollout. The model is evaluated on established world-model benchmarks, ENUMA-Bench, and human preference comparisons.